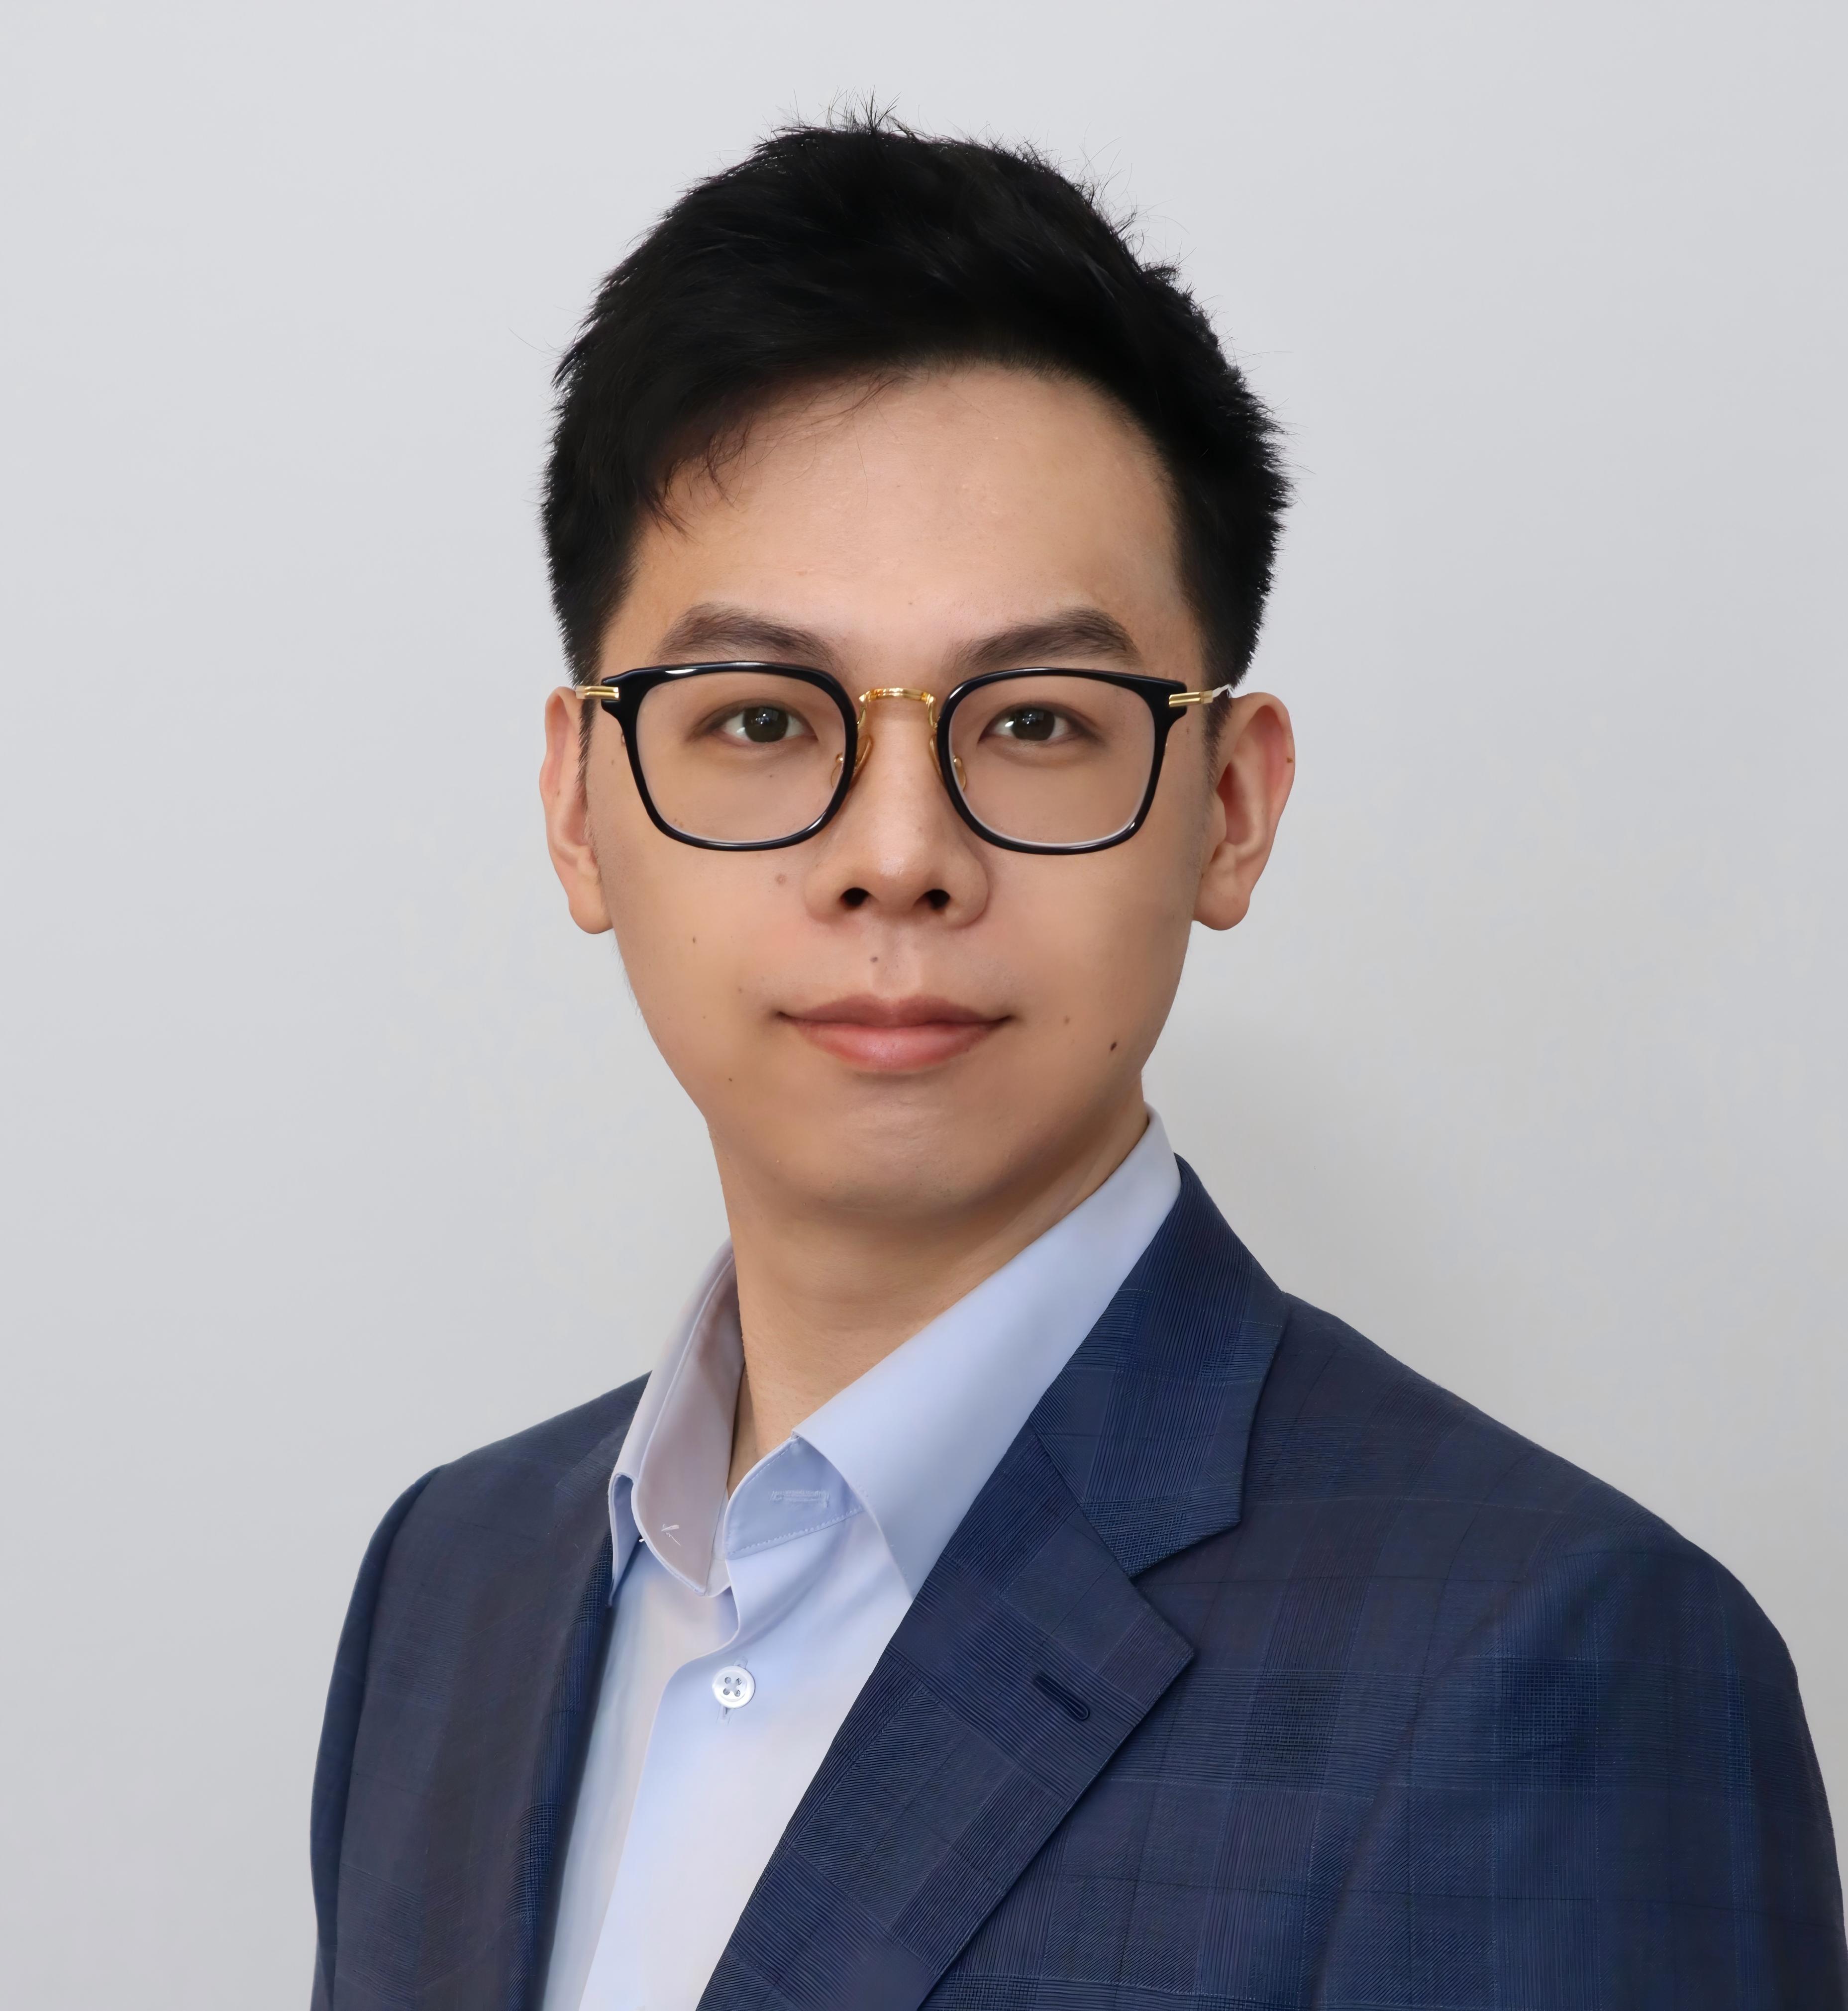
Ruiqi Wang
/ Ray-chee Wong /
I am a Postdoctoral Research Fellow at the University of Southern California, working with Professor Erdem Bıyık in the LiRA Lab. I received my Ph.D. from Purdue University, where I worked with Professor B.C. Min in the SMART Lab.
My research focuses on robot learning from humans to close the last mile of embodied AI. Robotic foundation models pretrained at scale bring broad capabilities, yet real-world deployment presents unfamiliar tasks, unforeseen situations, and users with their own expectations. Human feedback communicates what success means in each setting, including goals, preferences, and constraints that pretraining alone cannot fully specify. I build methods that let robots bridge this gap through the feedback people naturally provide: preferences, language, and implicit signals.
My work mainly asks three questions
- How can robots learn more from less human feedback? I use foundation models as synthetic teachers to amplify sparse human feedback into rich supervision, enabling robots to learn beyond the examples people explicitly evaluate.
- How can robots capture what people actually want? Human feedback is coarse, noisy, and often comes from many people who disagree. I develop reward learning methods that attribute holistic judgments to the specific behaviors that matter and model diverse, even conflicting, preferences across a crowd, yielding rewards that faithfully reflect human intent.
- How can robots generalize and adapt beyond what they were taught? I study how to distill human intent into reusable structure that transfers across tasks, users, and embodiments, and how robots can adapt to new people at deployment, whether by steering a pretrained policy or by inferring intent in context from multimodal feedback, without retraining.
Together, these directions aim to make robots easier to teach, more faithful to human intent, and quicker to adapt to new tasks and the people they work with.
News
- Sep 2026PrefO2O won the Best Paper Award at the HEAI Workshop, IROS 2026. Preprint coming soon.
- Sep 2026Serving as Associate Editor for Robot Learning at ICRA 2027.
- Jun 2026Two papers accepted at IROS 2026.
- May 2026Defended my Ph.D. dissertation at Purdue University.
- Sep 2025PRIMT accepted as an Oral (top 0.36%) at NeurIPS 2025.
- Jun 2025Two papers accepted at IROS 2025.
- Feb 2025Multimodal audio-based disease prediction accepted at IEEE/ACM T-ASLP.
- Jan 2025Three papers (including one RA-L transfer) accepted at ICRA 2025.
- Jan 2025PrefCLM accepted at IEEE Robotics and Automation Letters.
- Dec 2024Arjun (mentored undergrad) won First Place at the Purdue Fall Undergraduate Research Expo.
- Dec 2024Passed my Ph.D. dissertation proposal defense.
- Nov 2024Cognitive load-based affective workload allocation accepted at IEEE T-HMS.
- Jul 2024MOCAS dataset accepted at IEEE Transactions on Affective Computing.
- Feb 2024Attention-enhanced hierarchical RL for task allocation accepted at IEEE RA-L.
- Jan 2024SAMARL accepted at ICRA 2024.
- Jan 2024Husformer accepted at IEEE T-CDS.
- Jun 2023Two papers accepted at IROS 2023: ITA-AtRL and NaviSTAR.
- Jun 2022Feedback-efficient active preference learning accepted at IROS 2022.
Selected Publications
† Equal contribution · § Work I mentored · See all 19 publications →
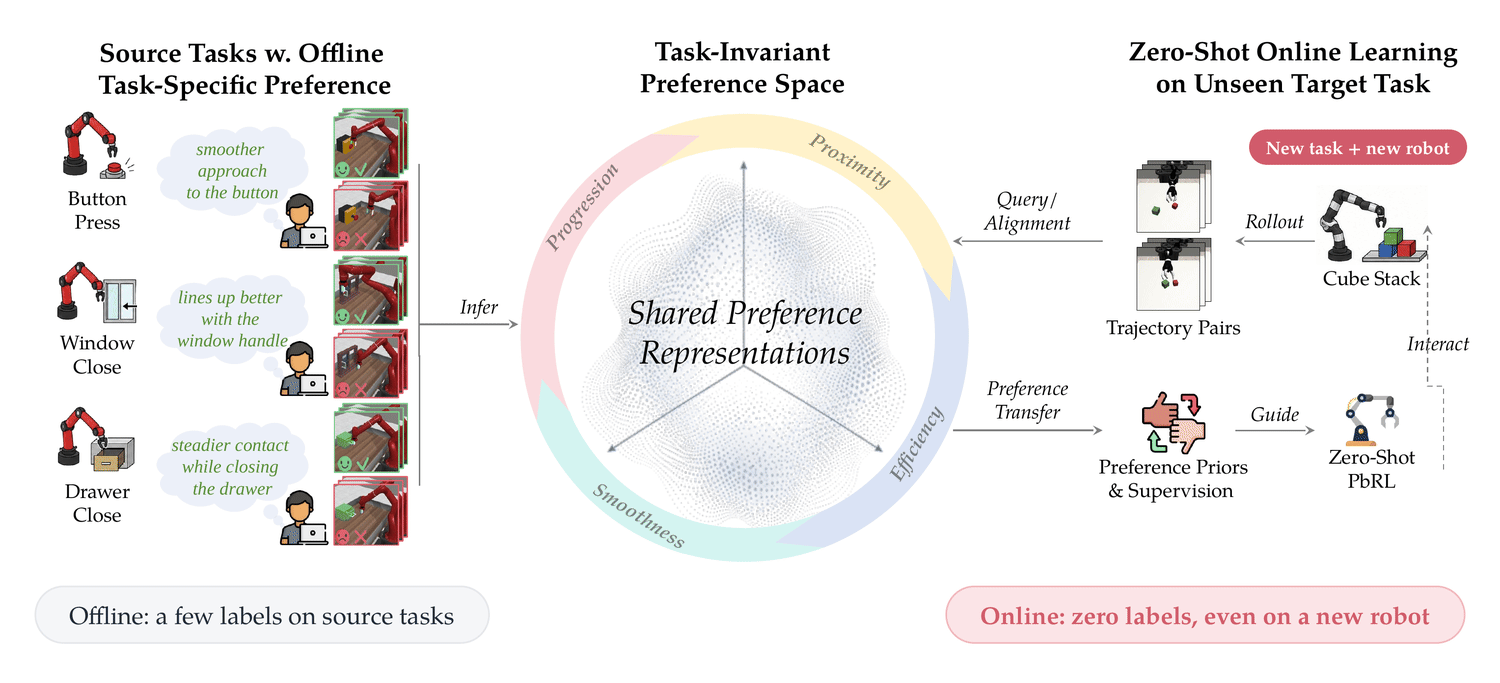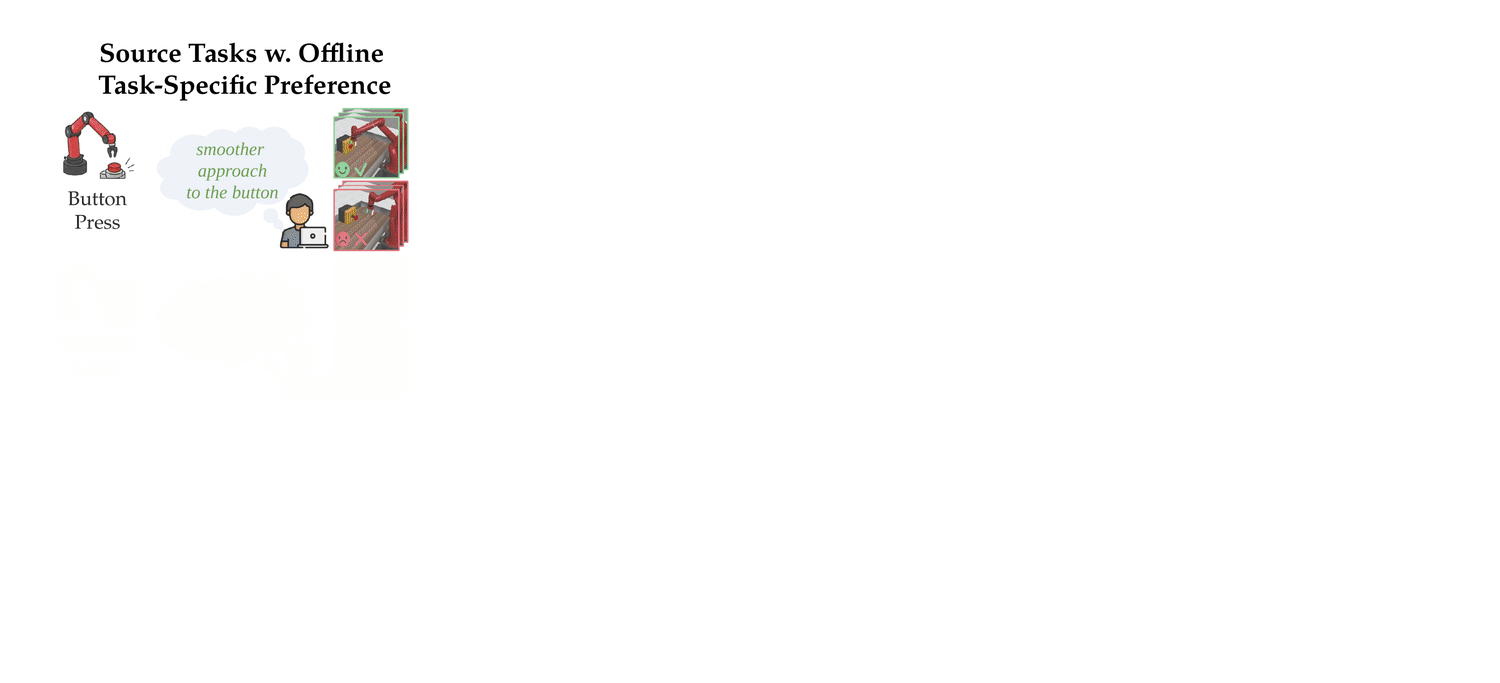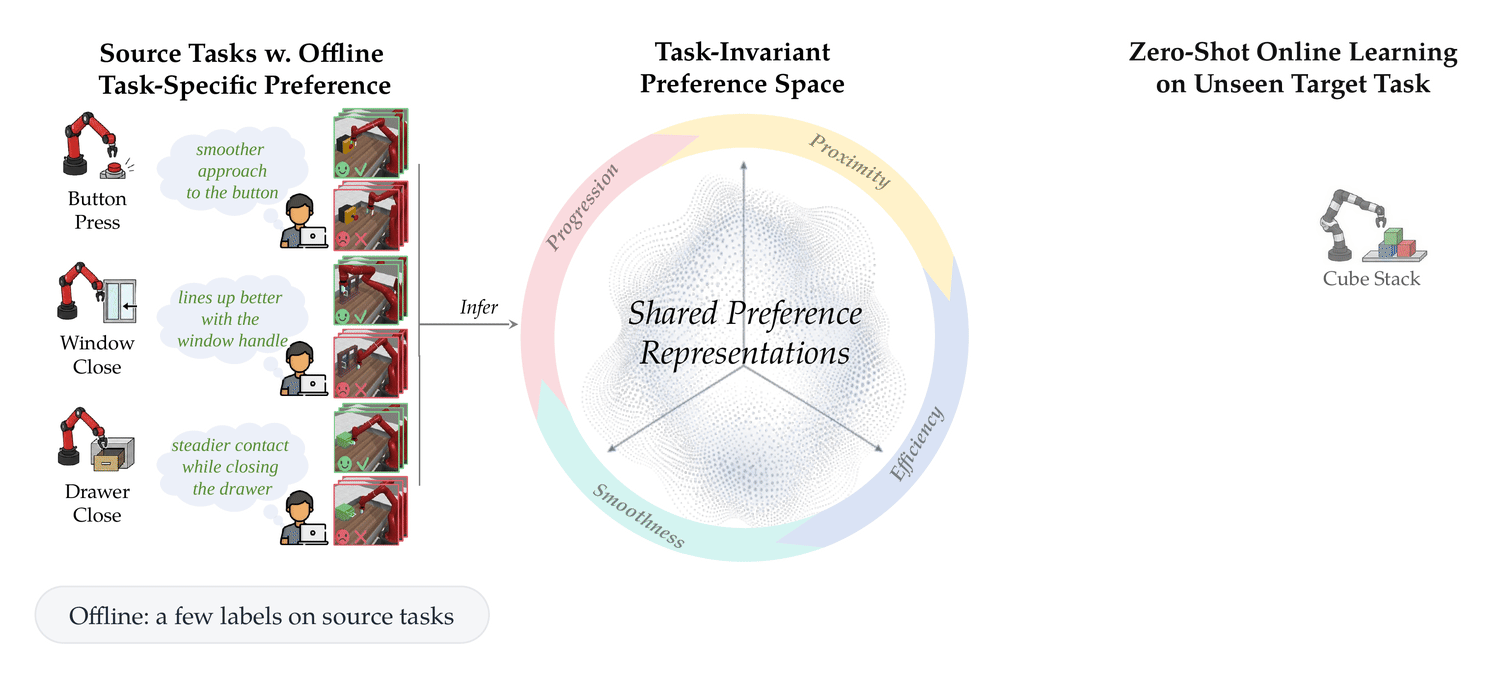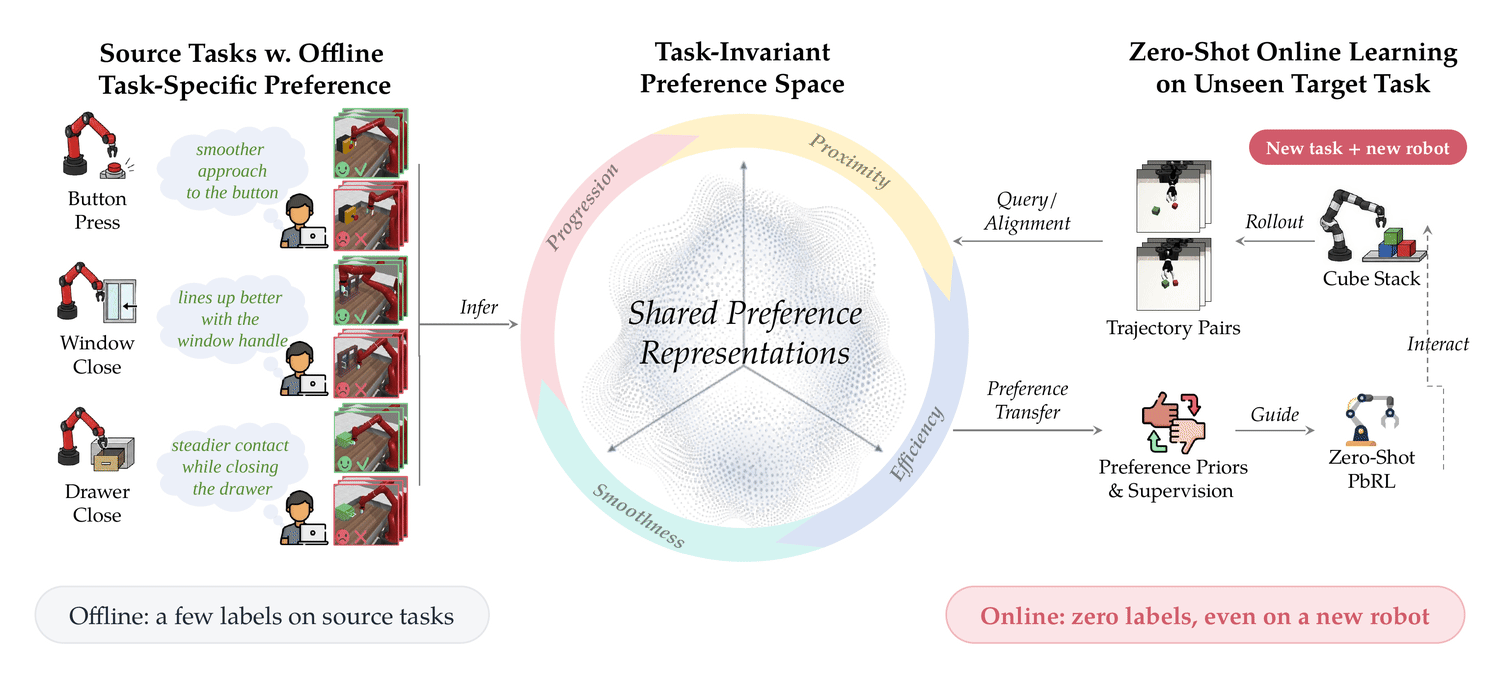
PrefO2O: Zero-Shot Preference-Based Reinforcement Learning via Offline-to-Online Latent Preference Transfer
HEAI Workshop, IROS 2026 Best Paper Award
Learn preferences once, transfer them across tasks and robots: extracting task-invariant preference structure enables zero-shot preference-based RL on unseen tasks and embodiments.
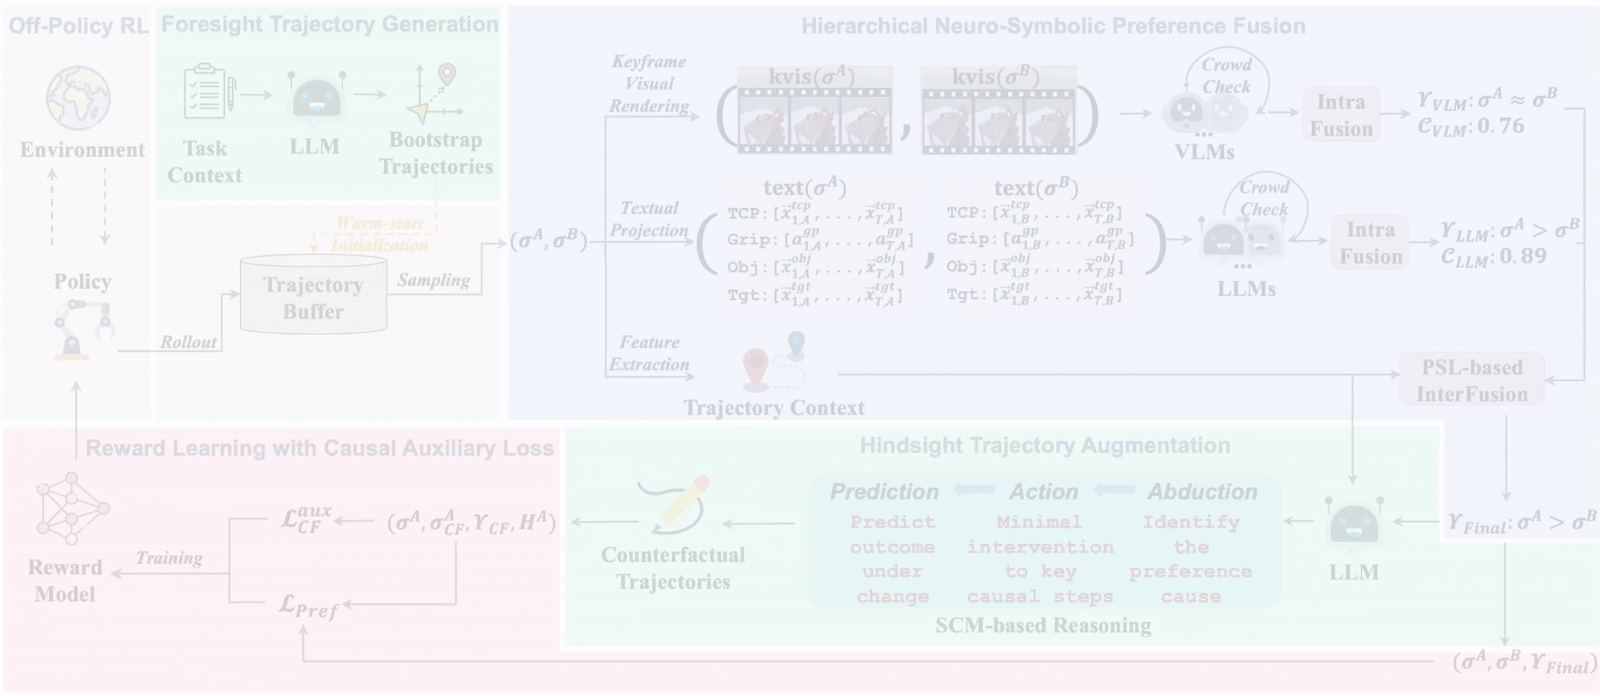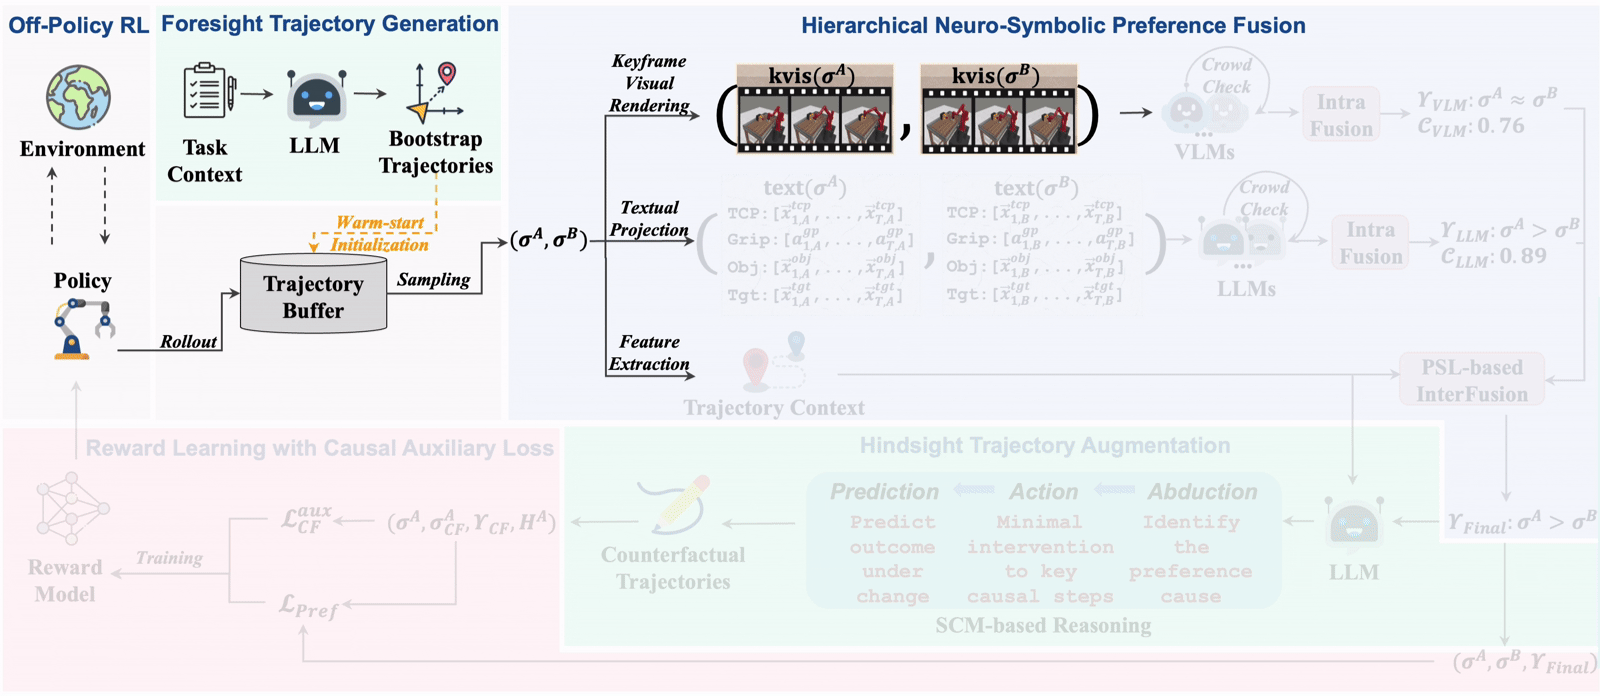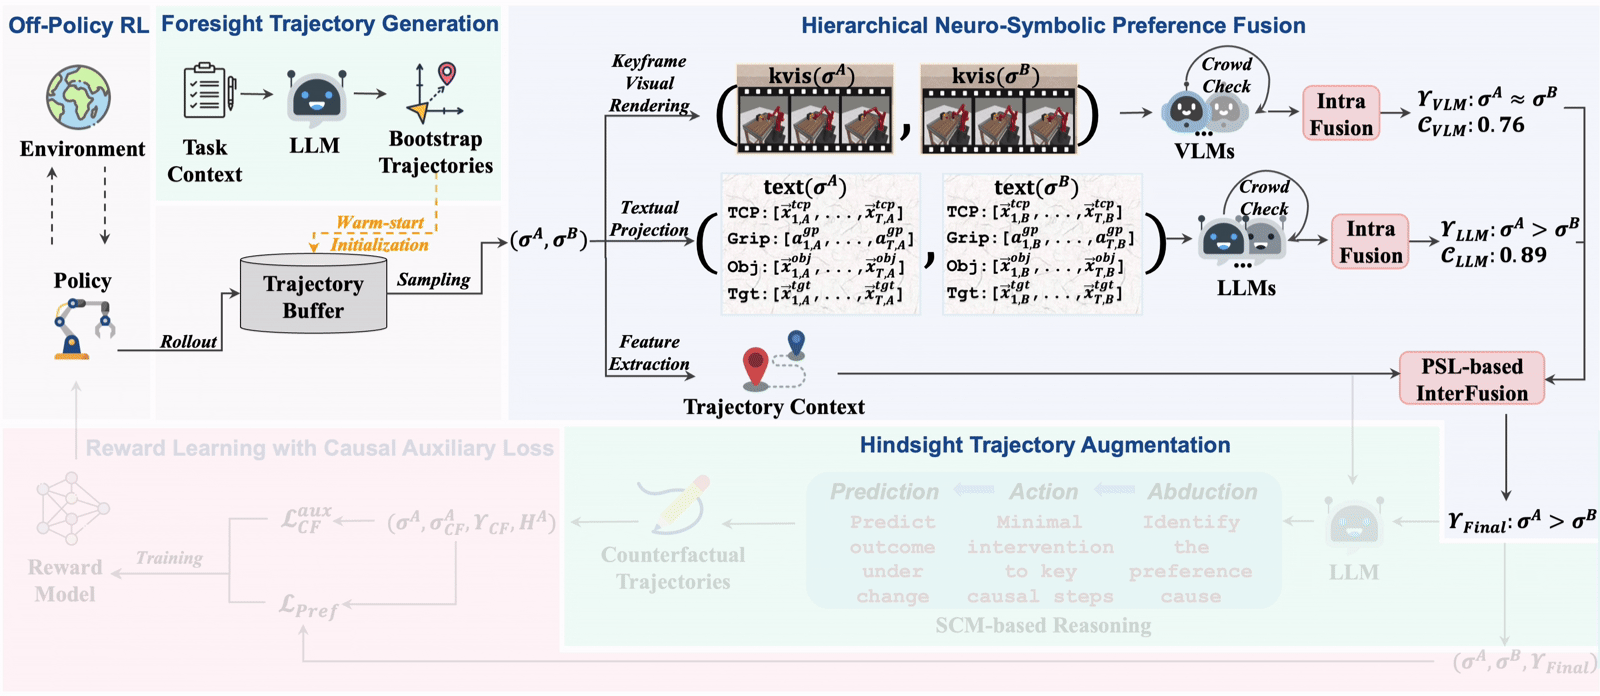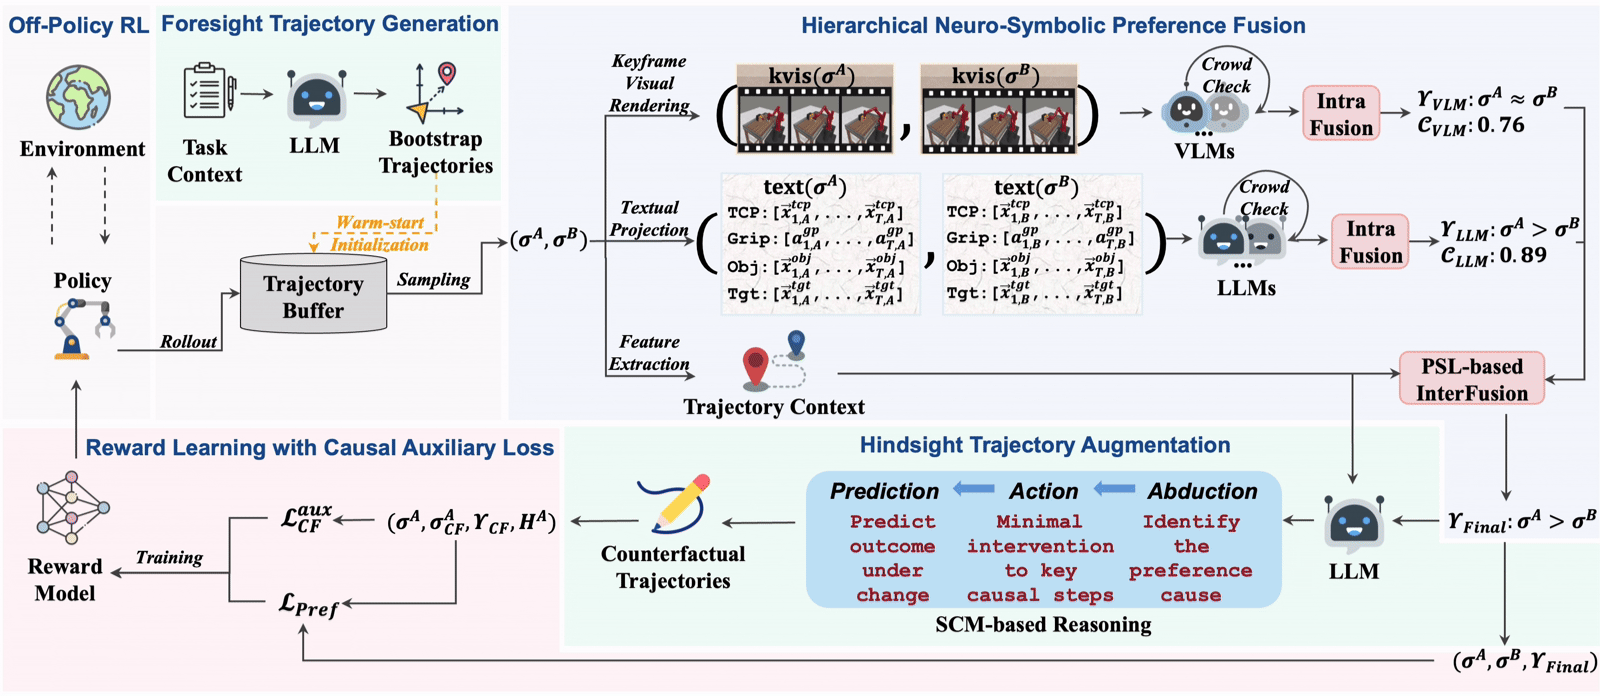
PRIMT: Preference-based Reinforcement Learning with Multimodal Feedback and Trajectory Synthesis from Foundation Models
NeurIPS 2025 Oral · Top 0.36%
Turn sparse human preferences into richer supervision: foundation models evaluate robot behavior multimodally and use preference-conditioned foresight and hindsight counterfactuals to explain which behaviors matter and why.
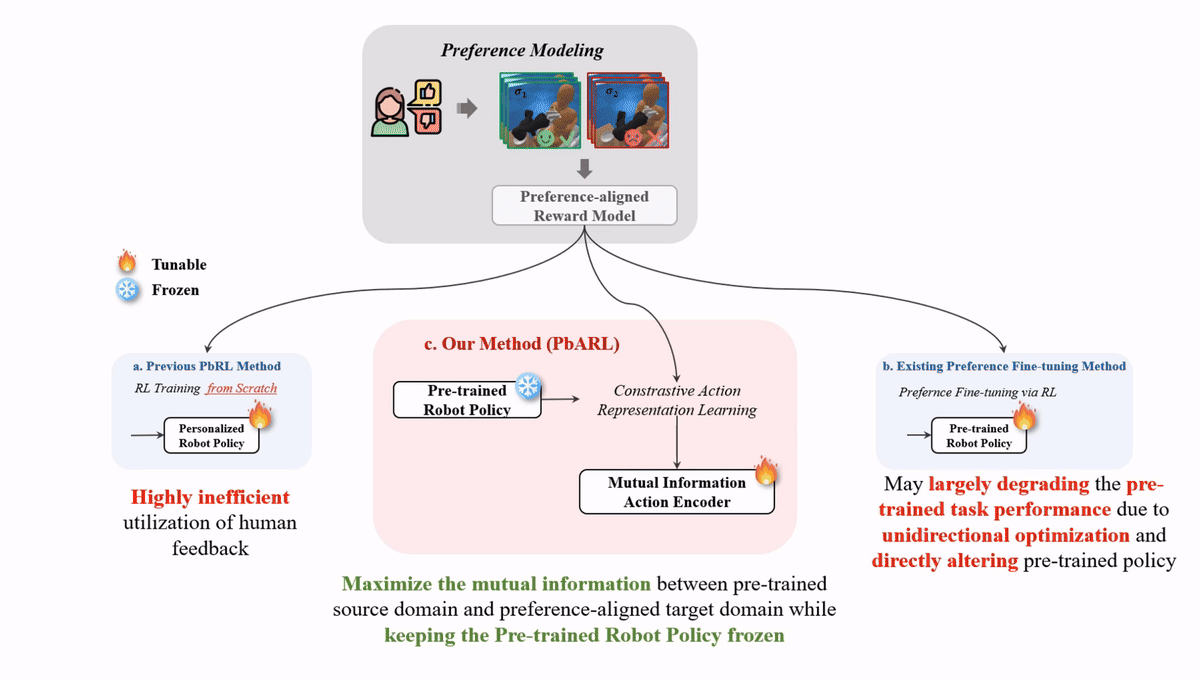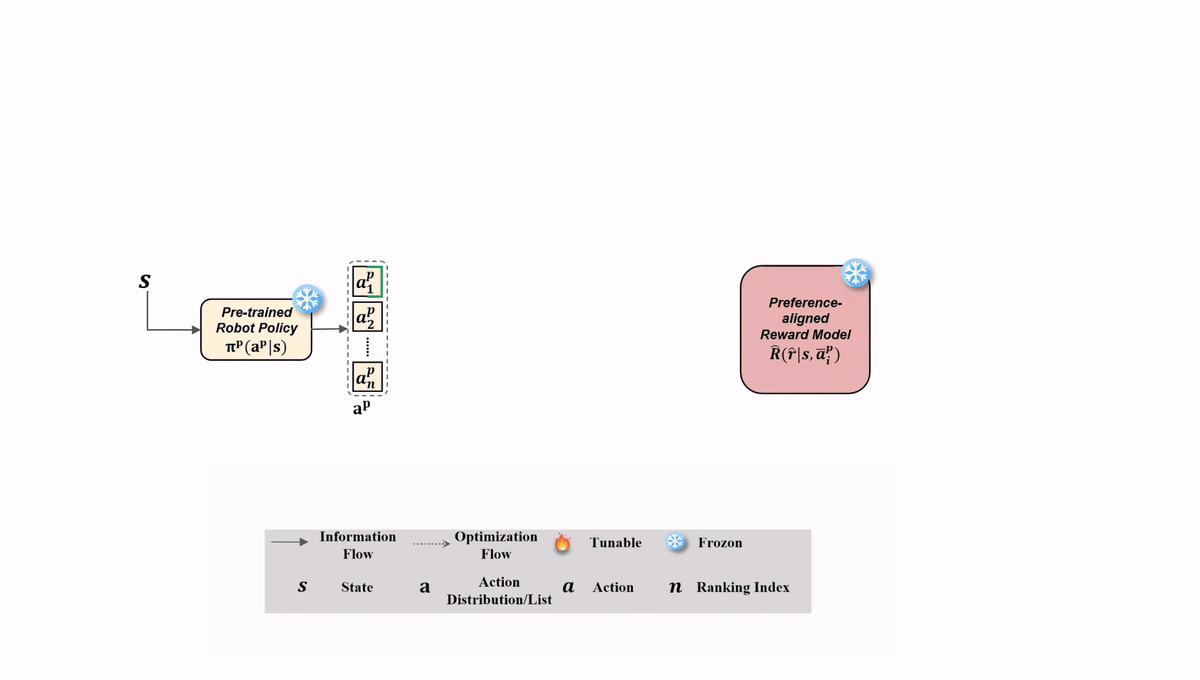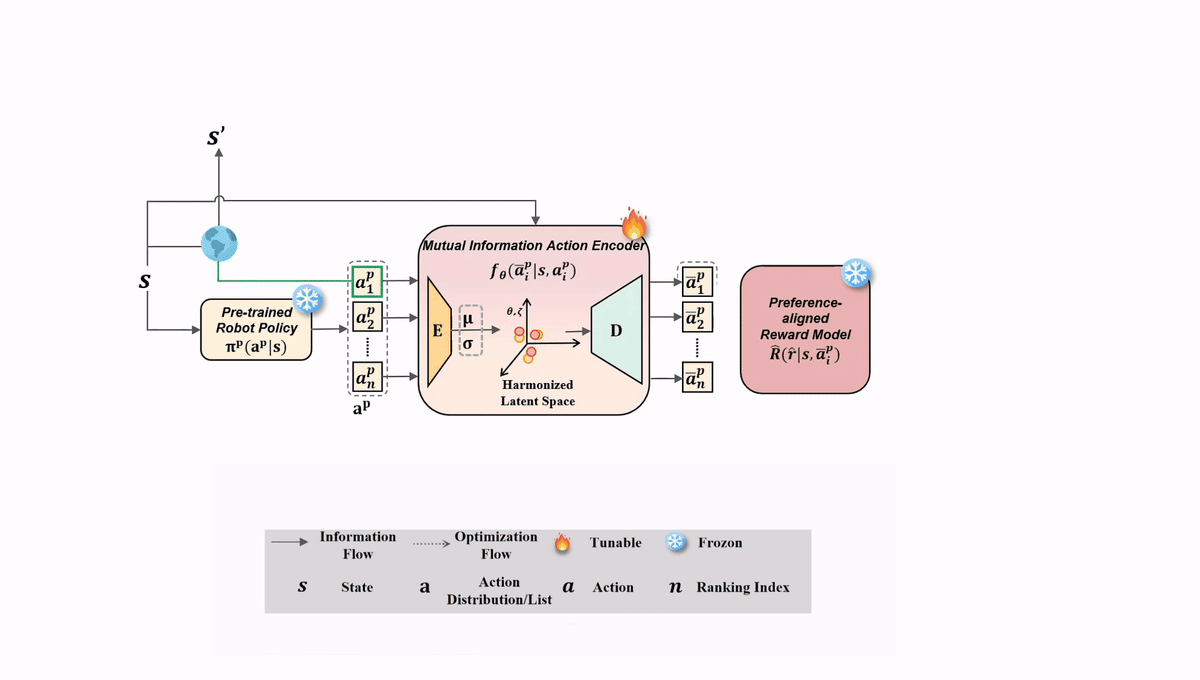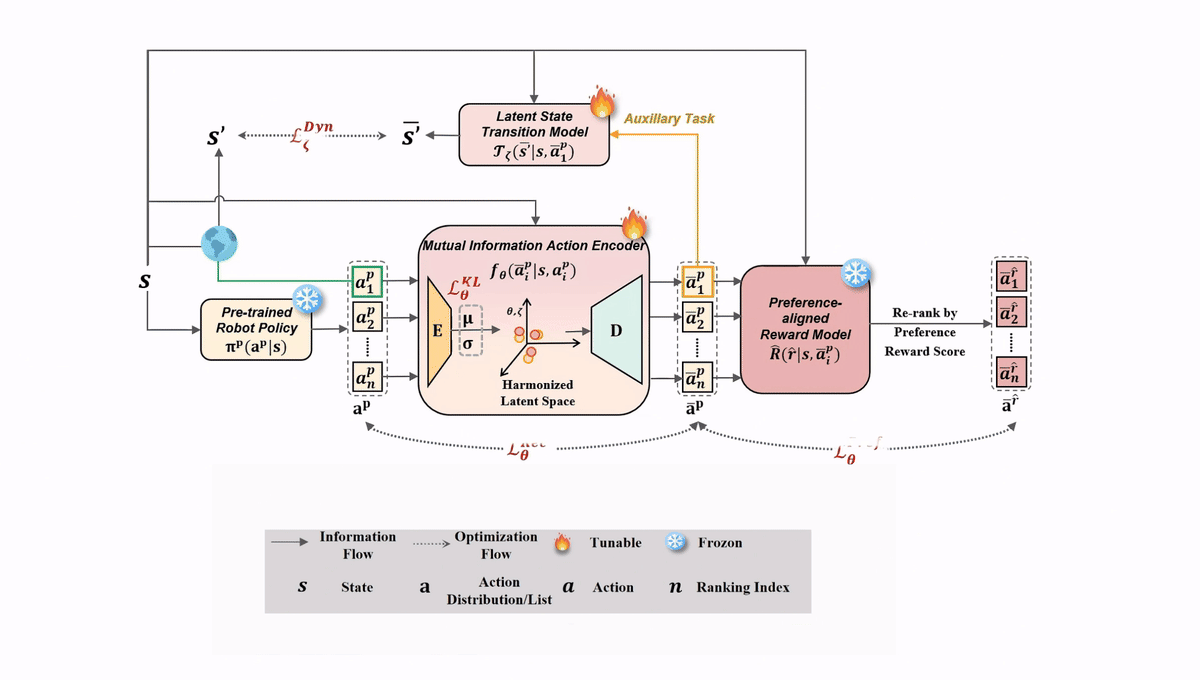
Personalization in Human-Robot Interaction through Preference-based Action Representation Learning
ICRA 2025
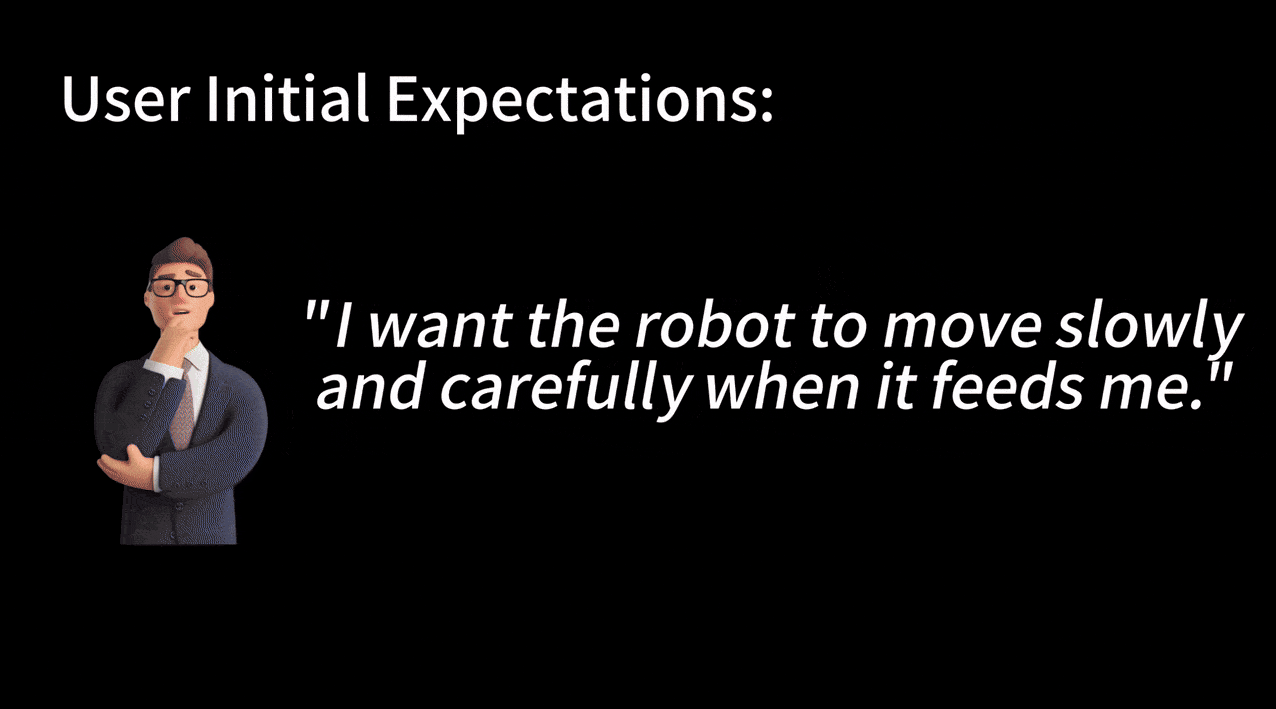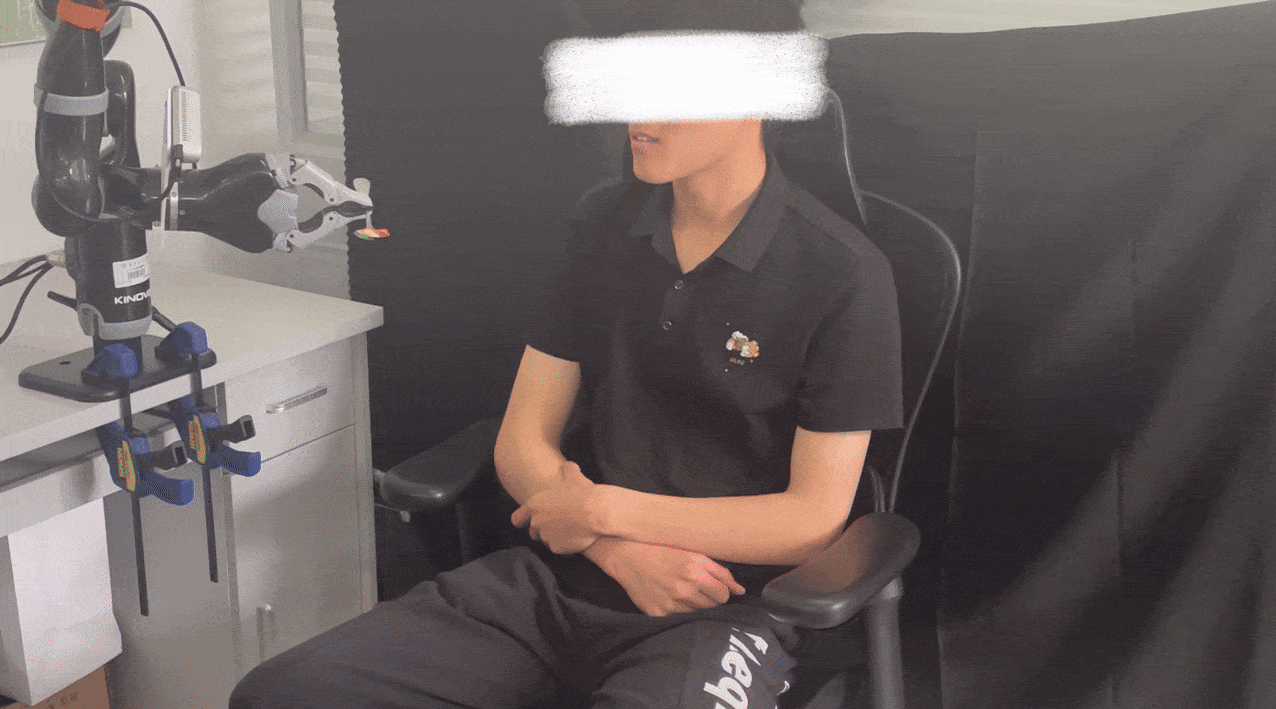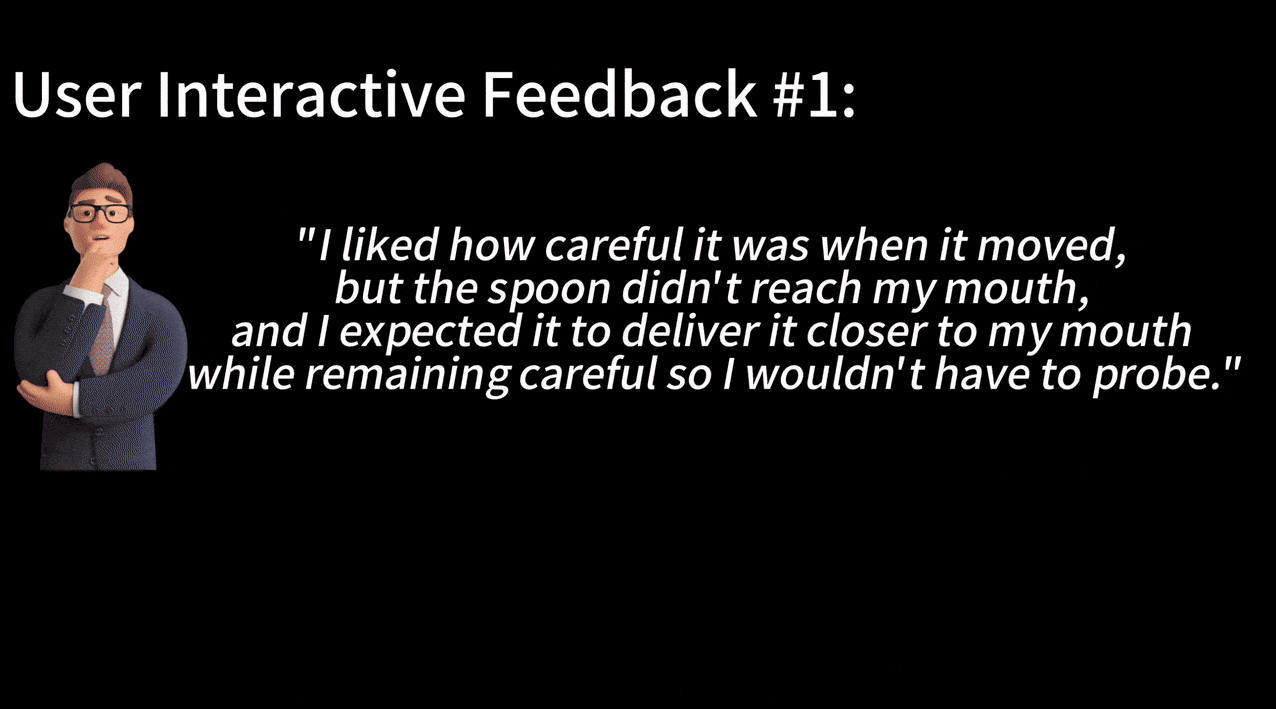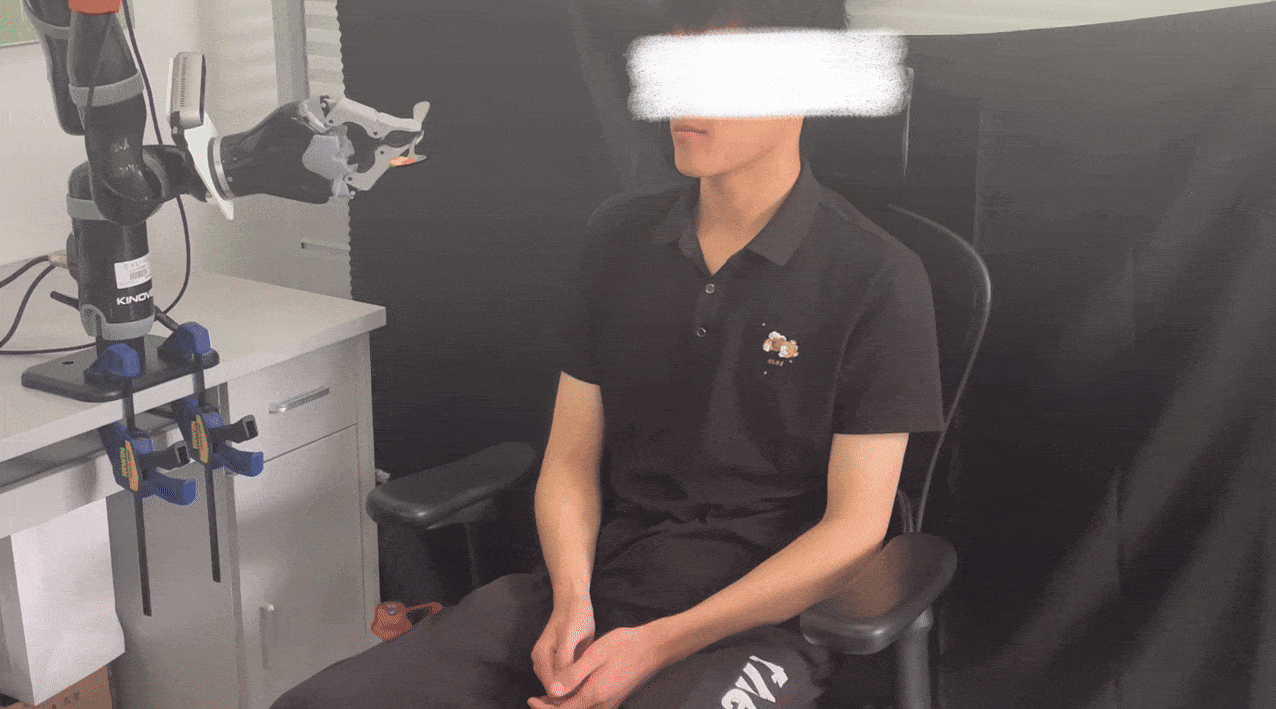
Personalize robot behavior by steering a pretrained policy at test time: a learned latent action space enables efficient adaptation to individual preferences while maintaining task performance.
PrefCLM: Enhancing Preference-based Reinforcement Learning with Crowdsourced Large Language Models
IEEE RA-L 2025
Scale preference feedback with a crowd of LLMs, and personalize it with human guidance: multiple LLM evaluators supply judgments that human input refines toward individual preferences.
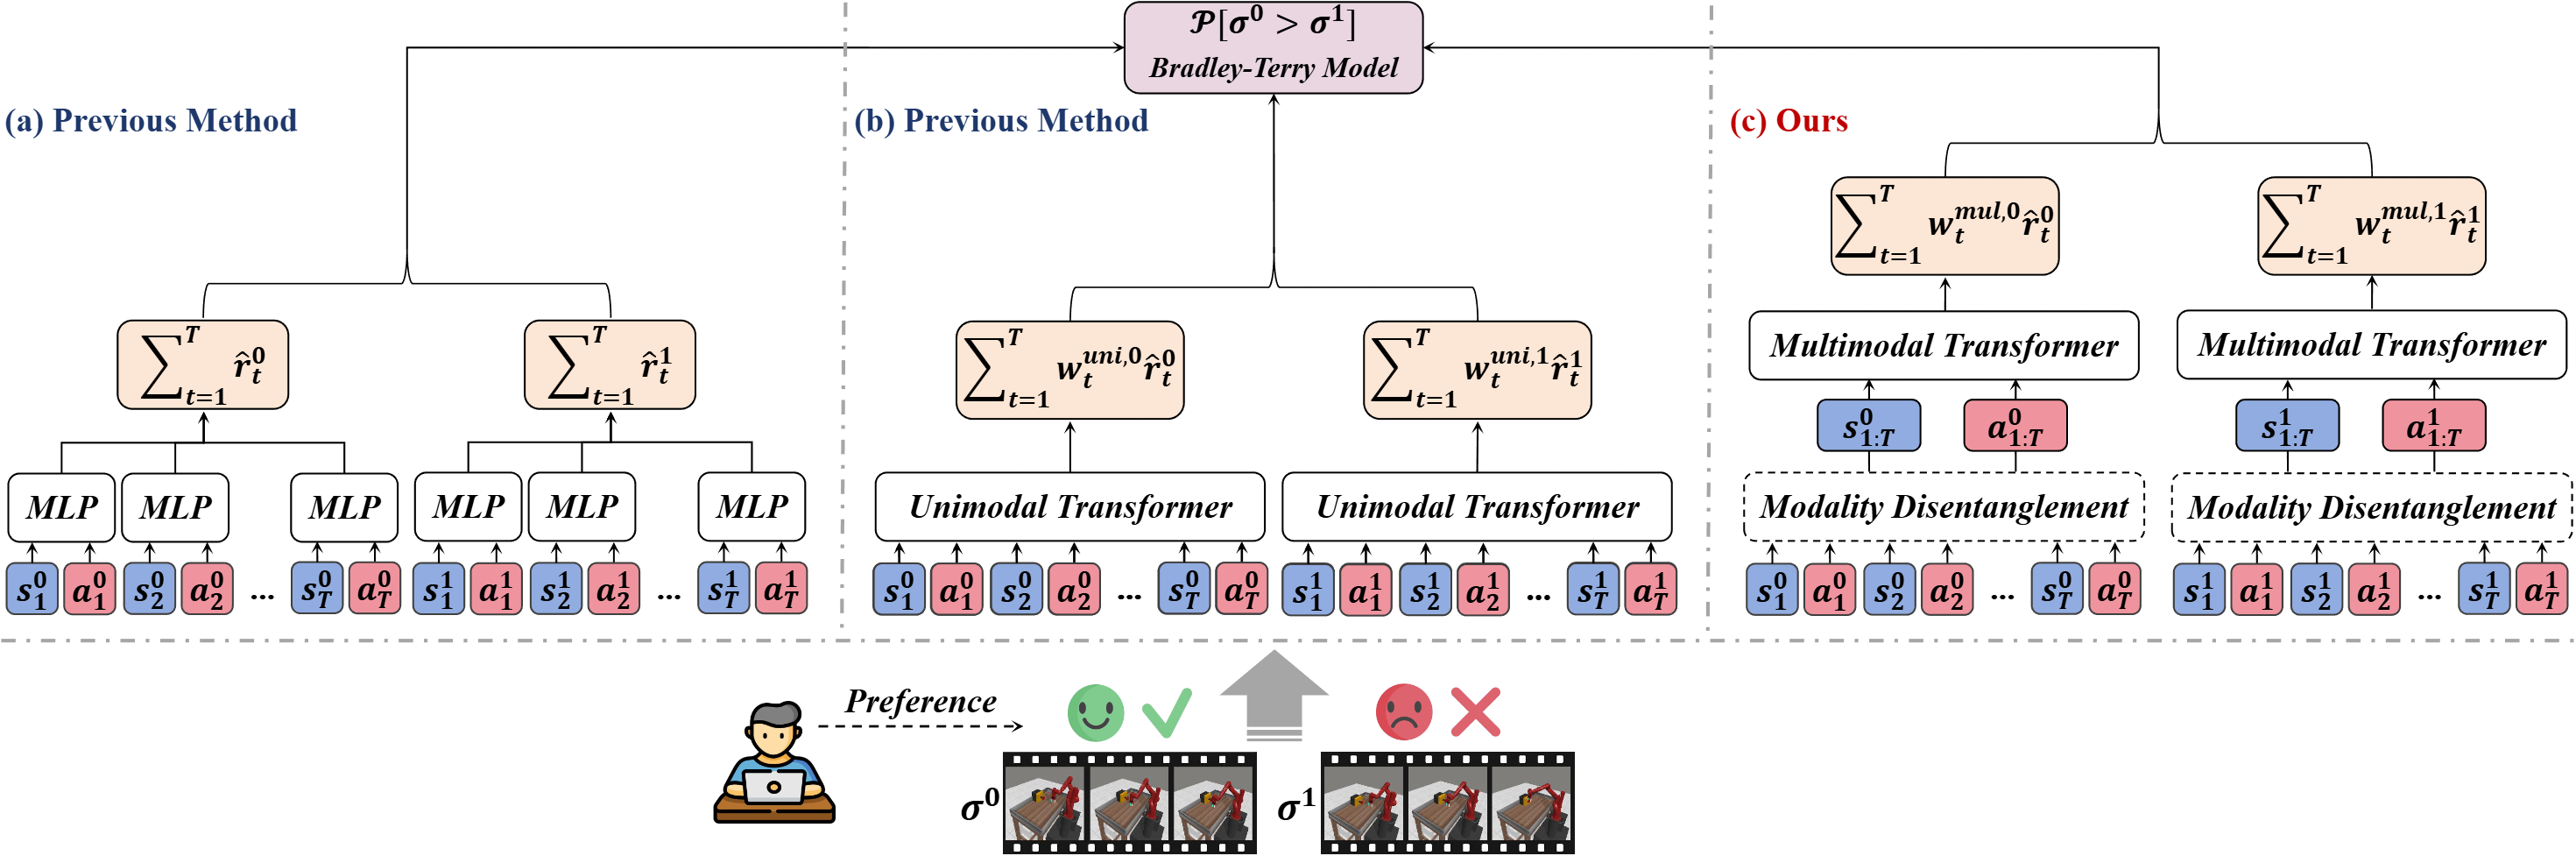
PrefMMT: Modeling Human Preferences in Preference-based Reinforcement Learning with Multimodal Transformers
IROS 2025
Locate the behavioral details behind trajectory-level preferences: modeling temporal dependencies and state–action interactions enables fine-grained credit assignment.

PrefMoE: Robust Preference Modeling with Mixture-of-Experts Reward Learning
IROS 2026
Learn from a crowd without collapsing its preferences into one: a mixture-of-experts reward model captures diverse and conflicting preferences in crowdsourced feedback.
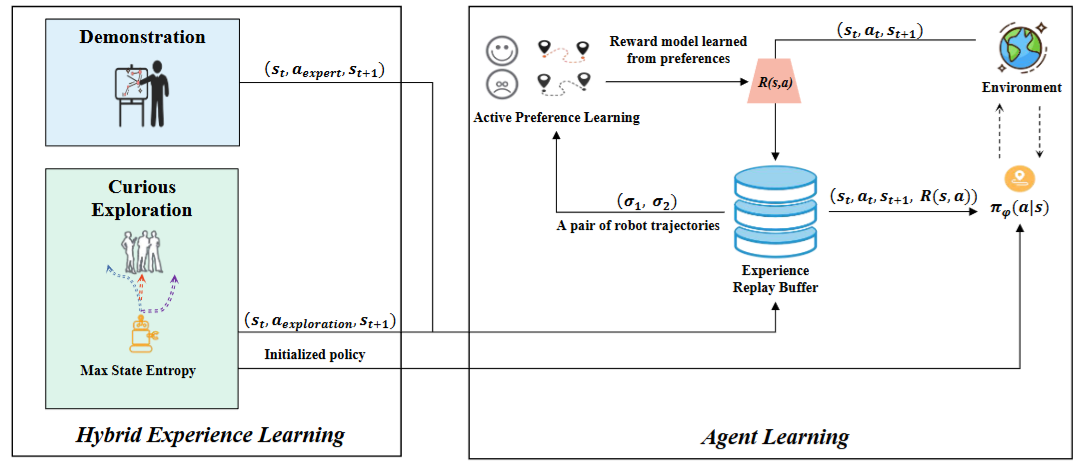
Feedback-efficient Active Preference Learning for Socially Aware Robot Navigation
IROS 2022
Use demonstrations to make preference queries more productive: expert demonstrations guide exploration, improving feedback efficiency in socially aware navigation.
Service
Associate Editor, ICRA 2027 (Robot Learning)
Reviewer: NeurIPS, ICLR, CoRL, ICRA, IROS, HRI · IEEE T-CYB, RA-L, T-HMS, ACM THRI